rlContinuousGaussianActor
R2026bStochastic Gaussian actor with a continuous action space for reinforcement learning agents
Since R2022a
Description
This object implements a function approximator to be used as a stochastic actor
within a reinforcement learning agent with a continuous action space. A continuous Gaussian
actor takes an environment observation as input and returns as output a random action sampled
from a parameterized Gaussian probability distribution, thereby implementing a parametrized
stochastic policy. After you create an rlContinuousGaussianActor object, use
it to create a suitable agent, such as an rlACAgent or rlPGAgent agent. For
more information on creating actors and critics, see Create Actors, Critics, and Policy Objects.
Creation
Description
actor = rlContinuousGaussianActor(net,observationInfo,actionInfo,Name=Value)net as approximation model.
You must use the name-value pair arguments ActionMeanOutputNames
and ActionStandardDeviationOutputNames to specify the names of the
network output layers that return the mean and standard deviation of each component of the
action, respectively. The actor uses the output of these two layers to represent the
Gaussian probability distribution from which the action is sampled.
Note
actor does not enforce constraints set by the action
specification. When using this actor in a different agent than SAC, you must enforce
action space constraints within the environment.
You can also specify the ObservationInputNames argument (to
explicitly associate the layers of your network with specific environment channels) and
the UseDevice property using optional name-value pair arguments. For
example, to use a GPU for prediction, specify UseDevice="gpu".
Input Arguments
Name-Value Arguments
Properties
Object Functions
rlACAgent | Actor-critic (AC) reinforcement learning agent |
rlPGAgent | Policy gradient (PG) reinforcement learning agent |
rlPPOAgent | Proximal policy optimization (PPO) reinforcement learning agent |
rlSACAgent | Soft actor-critic (SAC) reinforcement learning agent |
getAction | Obtain action from agent, actor, or policy object given environment observations |
evaluate | Evaluate function approximator object given observation (or observation-action) input data |
gradient | (Not recommended) Evaluate gradient of function approximator object given observation and action input data |
accelerate | (Not recommended) Option to accelerate computation of gradient for approximator object based on neural network |
getLearnableParameters | Obtain learnable parameter values from agent, function approximator, or policy object |
setLearnableParameters | Set learnable parameter values of agent, function approximator, or policy object |
setModel | Set approximation model in function approximator object |
getModel | Get approximation model from function approximator object |
Examples
Create an observation specification object (or alternatively use the getObservationInfo function to extract the specification object from an environment). For this example, define the observation space as a continuous six-dimensional space, so that there is a single observation channel that carries a column vector containing five doubles.
obsInfo = rlNumericSpec([5 1]);
Create an action specification object (or alternatively use the getActionInfo function to extract the specification object from an environment). For this example, define the action space as a continuous three-dimensional space, so that the action channel carries a column vector containing three doubles, each between -10 and 10.
actInfo = rlNumericSpec([3 1], ...
    LowerLimit=-10, ...
    UpperLimit=10);
A continuous Gaussian actor implements a parameterized stochastic policy for a continuous action space. This actor takes an observation as input and returns as output a random action sampled from a Gaussian probability distribution.
To approximate the mean values and standard deviations of the Gaussian distribution, you must use a neural network with two output layers, each having as many elements as the dimension of the action space. One output layer must return a vector containing the mean values for each action dimension. The other must return a vector containing the standard deviation for each action dimension.
Note that standard deviations must be nonnegative and mean values must fall within the range of the action. Therefore the output layer that returns the standard deviations must be a softplus or ReLU layer, to enforce nonnegativity, while the output layer that returns the mean values must be a scaling layer immediately preceded by a tahnLayer, to scale the mean values to the output range. However, if you are going to use the actor within a SAC agent, do not add a tanhLayer and a scalingLayer as the last two nonlinear layer in the mean output path. For more information, see Soft Actor-Critic (SAC) Agent.
For this example the environment has only one observation channel and therefore the network has only one input layer. Note that prod(obsInfo.Dimension) and prod(actInfo.Dimension) return the number of dimensions of the observation and action spaces, respectively, regardless of whether they are arranged as row vectors, column vectors, or matrices.
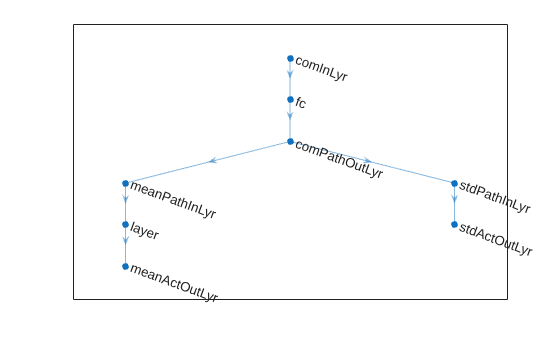
Define each network path as an array of layer objects, and assign names to the input and output layers of each path. These names allow you to connect the paths and then later explicitly associate the network input and output layers with the appropriate environment channel.
% Common input path layers
comPath = [
    featureInputLayer( ...
        prod(obsInfo.Dimension), ...
        Name="comInLyr");
    fullyConnectedLayer(prod(actInfo.Dimension));
    reluLayer(Name="comPathOutLyr")
    ];

% Path layers for mean value
% Using scalingLayer to scale range from (-1,1) to (-10,10)
meanPath = [
    fullyConnectedLayer(prod(actInfo.Dimension),Name="meanPathInLyr");

    % DO NOT USE following lines if actor is used for a SAC agent
    tanhLayer;
    scalingLayer(Name="meanActOutLyr",Scale=actInfo.UpperLimit)

    ];

% Path layers for standard deviations
% Using softplus layer to make them non negative
sdevPath = [
    fullyConnectedLayer(prod(actInfo.Dimension),Name="stdPathInLyr");
    softplusLayer(Name="stdActOutLyr")
    ];
Assemble dlnetwork object.
net = dlnetwork();
net = addLayers(net,comPath);
net = addLayers(net,meanPath);
net = addLayers(net,sdevPath);
Connect layers.
net = connectLayers(net,"comPathOutLyr","meanPathInLyr/in");
net = connectLayers(net,"comPathOutLyr","stdPathInLyr/in");
Plot the network.
plot(net)
Initialize network and display the number of learnable parameters (weights).
net = initialize(net);
summary(net)
   Initialized: true

   Number of learnables: 42

   Inputs:
      1   'comInLyr'   5 features
Create the actor with rlContinuousGaussianActor, using the network, the observation and action specification objects, and the names of the network input and output layers.
actor = rlContinuousGaussianActor(net, obsInfo, actInfo, ...
    ActionMeanOutputNames="meanActOutLyr", ...
    ActionStandardDeviationOutputNames="stdActOutLyr", ...
    ObservationInputNames="comInLyr");
To check your actor, use the getAction function to return an action from a random observation vector, using the current network weights.
act = getAction(actor,{rand(obsInfo.Dimension)}); Display the action.
act{1}ans = 3×1 single column vector
-7.6919
6.0897
9.1692
Each of the three elements of the action vector is a random sample from the stochastic distribution with mean and standard deviation provided, as a function of the current observation, by the neural network. To return the Gaussian distribution of the action, given an observation, use evaluate.
dist = evaluate(actor,{rand(obsInfo.Dimension)});Display the vector of mean values.
dist{1}ans = 3×1 single column vector
-6.1829
3.6141
8.2286
Display the vector of standard deviations.
dist{2}ans = 3×1 single column vector
0.8991
0.9065
0.7513
You can now use the actor (along with a critic) to create an agent for the environment described by the given specification objects. Examples of agents that can work with continuous action and observation spaces, and use a continuous Gaussian actor, are rlACAgent, rlPGAgent, rlSACAgent, rlPPOAgent, and rlTRPOAgent.
For more information on creating approximator objects such as actors and critics, see Create Actors, Critics, and Policy Objects.
Extended Capabilities
Version History
Introduced in R2022a

