Main Content

ocrMoondream

R2026b

Recognize text in image using Moondream vision-language model (VLM)

Since R2026b

    Description

    Add-On Required: This feature requires the Computer Vision Toolbox Model for Moondream Vision Language Model add-on.

    text = ocrMoondream(mdModel,I) recognizes text in the image I using the Moondream™ vision-language model mdModel. The function returns the optical character recognition (OCR) information text, which include English text present in the input image without character-level metadata such as bounding boxes or confidence scores. When the input image does not contain text, the output might be a descriptive string of the image content rather than an empty result.

    text = ocrMoondream(mdModel,I,roi) recognizes text within one or more rectangular search regions roi of the image I.

    text = ocrMoondream(mdModel,imds) recognizes text in all of the images returned by the read function of the datastore imds.

    text = ocrMoondream(___,Name=Value) specifies options using one or more name-value arguments, in addition to any combination of input arguments from previous syntaxes. For example, PromptStyle="Transcribe the text" specifies to include all visible text in the input image without any strict, spatial, reading order.

    example

    Examples

    collapse all

    Load a pretrained Moondream vision-language model with approximately 1.6 billion parameters into the workspace.

    mdModel = moondream("moondream-1.6B");

    Load an image into the workspace, and display the image.

    I = imread("handicapSign.jpg");
    imshow(I)
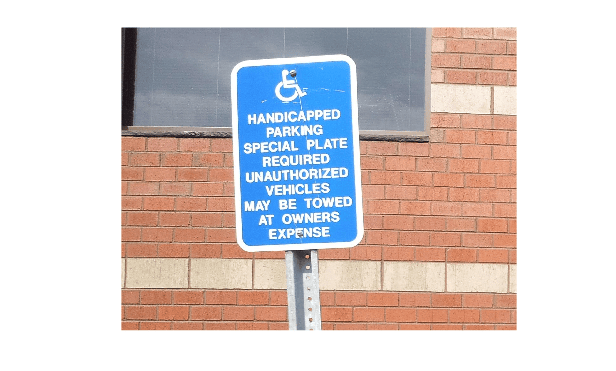
    Figure contains an axes object. The hidden axes object contains an object of type image.

    Define a rectangular region of interest in which to recognize text within the input image.

    roi = [370 246 363 423];

    Recognize text within the ROI using the ocrMoondream object function.

    text = ocrMoondream(mdModel,I,roi);
    display(text)
    text = 
    "HANDICAPPED PARKING SPECIAL PLATE REQUIRED UNAUTHORIZED VEHICLES MAY BE TOWED AT OWNERS EXPENSE"
    

    Input Arguments

    collapse all

    Moondream vision-language model, specified as a moondream object.

    Input image, specified as a numeric array of size H-by-W-by-C. You must specify real, nonsparse, grayscale or RGB images.

    • H— Height of the image.

    • W— Width of the image.

    • C— Number of channels in the image. The channel size of each image must be equal to the input channel size of the network. For example, for grayscale images, C must be 1. For RGB color images, it must be 3.

    Rectangular regions of interest, specified as a four-element row vector or M-by-4 matrix. If you specify this argument as a matrix, each row specifies the location of a rectangular region of interest in the image using the same format as the vector. The vector specifies a region of interest within the input image in the form [x y width height], where [x y] specifies the coordinates of the upper-left corner of the region, and [width height] specifies the size of the rectangular region of interest, in pixels. Each rectangle must be fully contained within the input image I.

    Datastore of images, specified as any type of datastore that returns image data. When using the read function of the datastore, it must return a table or a cell array with the image data in the first cell.

    Name-Value Arguments

    collapse all

    Specify optional pairs of arguments as Name1=Value1,...,NameN=ValueN, where Name is the argument name and Value is the corresponding value. Name-value arguments must appear after other arguments, but the order of the pairs does not matter.

    Example: ocrMoondream(mdModel,I,PromptStyle="Transcribe the text") specifies to include all visible text in the input image without any strict, spatial, reading order.

    Text reading and arrangement style of the recognized text, specified as one of these options:

    • "Transcribe the text in natural reading order" — The output follows standard English left-to-right, top-to-bottom reading conventions, preserving logical reading flow across columns, sections, and layouts. Use this value for structured documents such as invoices, forms, reports, letters, multi-column layouts such as newspapers, magazines, and any content where reading sequence matters. The model respects the spatial layout, and maintains field ordering as a human reader would naturally follow.

    • "Transcribe the text" — The output includes all visible text without any strict, spatial, reading order. The text might be grouped by visual proximity or semantic relationships rather than conventional top-to-bottom, left-to-right patterns. Use this value for irregular layouts such as posters, advertisements, product packaging, scattered text elements such as street signs, labels, and cases where the exact sequence of the text is not critical.

    • "Read the text" — The output includes text for readability and comprehension, as if reading aloud. The text might contain implicit spacing, punctuation, or natural language formatting, and be focused on making the text understandable rather than providing an exact transcription. Use this value for accessibility applications such as screen readers, audio conversion, and cases where readability matters more than exact character-for-character accuracy.

    If none of these values produce satisfactory results for your image layout or reading task, use the queryImage function to provide custom and task-specific instructions.

    Hardware resource on which to run the detector, specified as "auto", "gpu", or "cpu". The table shows the valid hardware resource values.

    Resource Action
    "auto" Use a GPU if it is available. Otherwise, use the CPU.
    "gpu" Use the GPU. To use a GPU, you must have Parallel Computing Toolbox™ and a CUDA® enabled NVIDIA® GPU. Currently, GPU execution is supported for only the pretrained Moondream vision-language model with approximately 1.6 billion parameters. If a suitable GPU is not available, the function returns an error. For information about the supported compute capabilities, see GPU Computing Requirements (Parallel Computing Toolbox).
    "cpu" Use the CPU.

    Output Arguments

    collapse all

    Recognized text, returned as one of these options, depending on the format of the input image.

    • I, a single RGB image with single ROI — String scalar.

    • Input is a single RGB or grayscale image with multiple ROIs — M-by-1 vector of strings, in which each element is the recognized text for the corresponding ROI.

    • Input is imds, an image datastore — B-by-1 vector of strings, where B is the number of images in the datastore imds.

    When the input image does not contain text, the output might be a descriptive string of the image content rather than an empty result.

    Tips

    • The quality of Moondream outputs can vary across different data domains. Validate its predictions using a data set from a domain similar to your intended application.

    Extended Capabilities

    expand all

    GPU Arrays
    Accelerate code by running on a graphics processing unit (GPU) using Parallel Computing Toolbox™.

    Version History

    Introduced in R2026b